
Your prompts, outputs, and models stay encrypted in use, unreadable to the host, the operator, and Arcium.

 Private alpha live

Encrypted Superintelligence
Run powerful AI on encrypted GPUs, keeping every prompt, file, and answer private.
What’s this?
The frontier of confidential AI
Arcium Blackthorn replaces hardware trust with math, running confidential AI on any Hopper, Blackwell GPU or HGX server.

The Unlock
Own your Intelligence
Blackthorn runs frontier AI on your most sensitive data, encrypted in use, under your control, readable by no one. Including us.
Run private AIAI clouds & inference platforms
Run bLLM on your GPUs to offer confidential inference, or use the Blackthorn API with nothing to operate. Either way, keys stay off the host.
Healthcare AI
Run inference and training on patient records, genomics, and clinical notes, unlocking new data sets for diagnosis, research and prevention.
Financial AI
Run models on the full book while keeping positions and customer data encrypted in use. Analyze sensitive data without exposing it to a provider.
Sovereign & Regulated AI
Run frontier AI over privileged data on infrastructure you control, with neither the operator nor an x86 TEE included in the trust chain.
Private alpha
Run encrypted intelligence today
Connect to Blackthorn via API or enable confidential inference on your own GPUs by installing bLLM.
Connect via API
The best open-weight models, pay-per-token, nothing to operate and not even Arcium reads the traffic.
Bring your own GPUs
bLLM turns your CC-capable NVIDIA fleet into more secure, lower-trust confidential compute with a simple software switch.
Request a dedicated unit
A full Blackthorn unit, yours alone. Run your own models on dedicated compute, encrypted end to end.
# Start the local client once
export BLLM_TOKEN="<your API token>"
python3 openai_server.py \
  --host https://bt-api.arcium.com \
  --roster identities.json
# -> OpenAI-compatible API on http://127.0.0.1:8000/v1 pip install openai
from openai import OpenAI

client = OpenAI(base_url="http://127.0.0.1:8000/v1", api_key="unused")  # auth is your BLLM_TOKEN

messages = [{"role": "user", "content": "What is the capital of France?"}]
reply = client.chat.completions.create(model="qwen3.5-0.8b-bllm", messages=messages, max_tokens=256)
print(reply.choices[0].message.content)

# Follow-ups: resend the earlier turns exactly as returned, plus one new user message
messages += [
    {"role": "assistant", "content": reply.choices[0].message.content},
    {"role": "user", "content": "And of Germany?"},
]
stream = client.chat.completions.create(model="qwen3.5-0.8b-bllm", messages=messages, stream=True)
for chunk in stream:
print(chunk.choices[0].delta.content or "", end="", flush=True) npm install openai
import OpenAI from "openai";

const client = new OpenAI({ baseURL: "http://127.0.0.1:8000/v1", apiKey: "unused" });

const stream = await client.chat.completions.create({
  model: "qwen3.5-0.8b-bllm",
  messages: [{ role: "user", content: "What is the capital of France?" }],
  stream: true,
});
for await (const chunk of stream) process.stdout.write(chunk.choices[0]?.delta?.content ?? "");curl http://127.0.0.1:8000/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{
"model": "qwen3.5-0.8b-bllm",
"messages": [{"role": "user", "content": "What is the capital of France?"}],
"max_tokens": 256
}'qwen3.5-0.8b-bllm OpenAI-compatible
SECURITY
The most secure confidential AI on Earth
Blackthorn replaces trust in vulnerable chips and operators with math no single company controls.
Explore docsScroll horizontally to explore the full diagram →
 outer SPDM layer, via AES-MPC
 Arcium Network
replaces the vulnerable CPU TEE and encrypts the outer channel with AES keys secret-shared across MPC nodes
 NVIDIA GPUConfidential Computing Mode
bLLM runs models in an encrypted region (CPR) controlled by the Arcium Network, outside the reach of the operator, the cloud & Arcium
You,
your prompts, files & secrets
encrypted with your inner keyUntrusted Relayer Host
relays the encrypted records; never sees plaintext
still encrypted end-to-end throughoutModel weights
open or proprietary, loaded encrypted
output returns, encrypted the same way
Encrypted Compute
Connect to NVIDIA Confidential-Computing GPUs
Join private Alpha to get access to compatible CC-enabled GPUs hardware, live today.
BT H100 HGX
 HopperBlackthorn
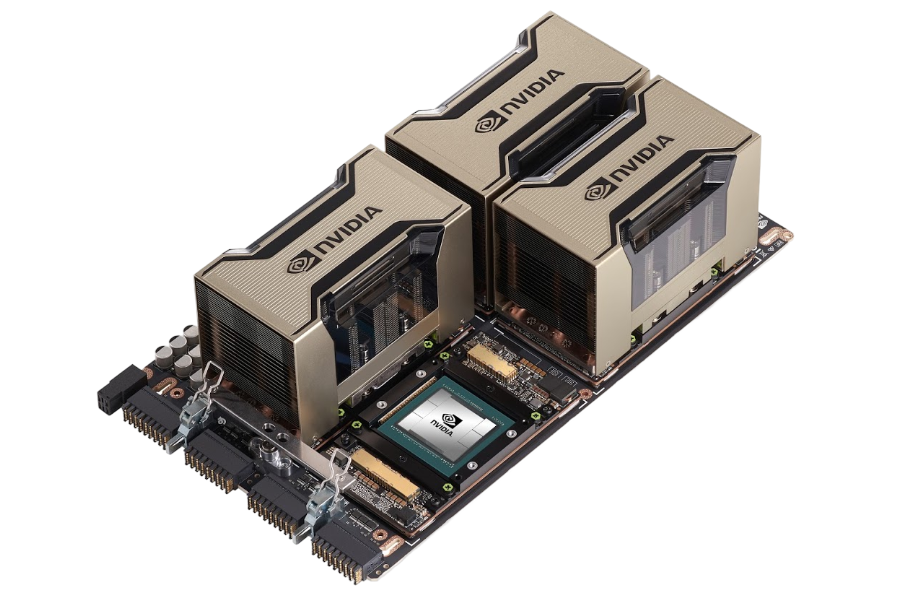
- Compute
- 8× H100 SXM
- GPU memory
- 640 GB HBM3
- Runtime
- bLLM, encrypted end to end
BT B200 HGX
BlackwellBlackthorn
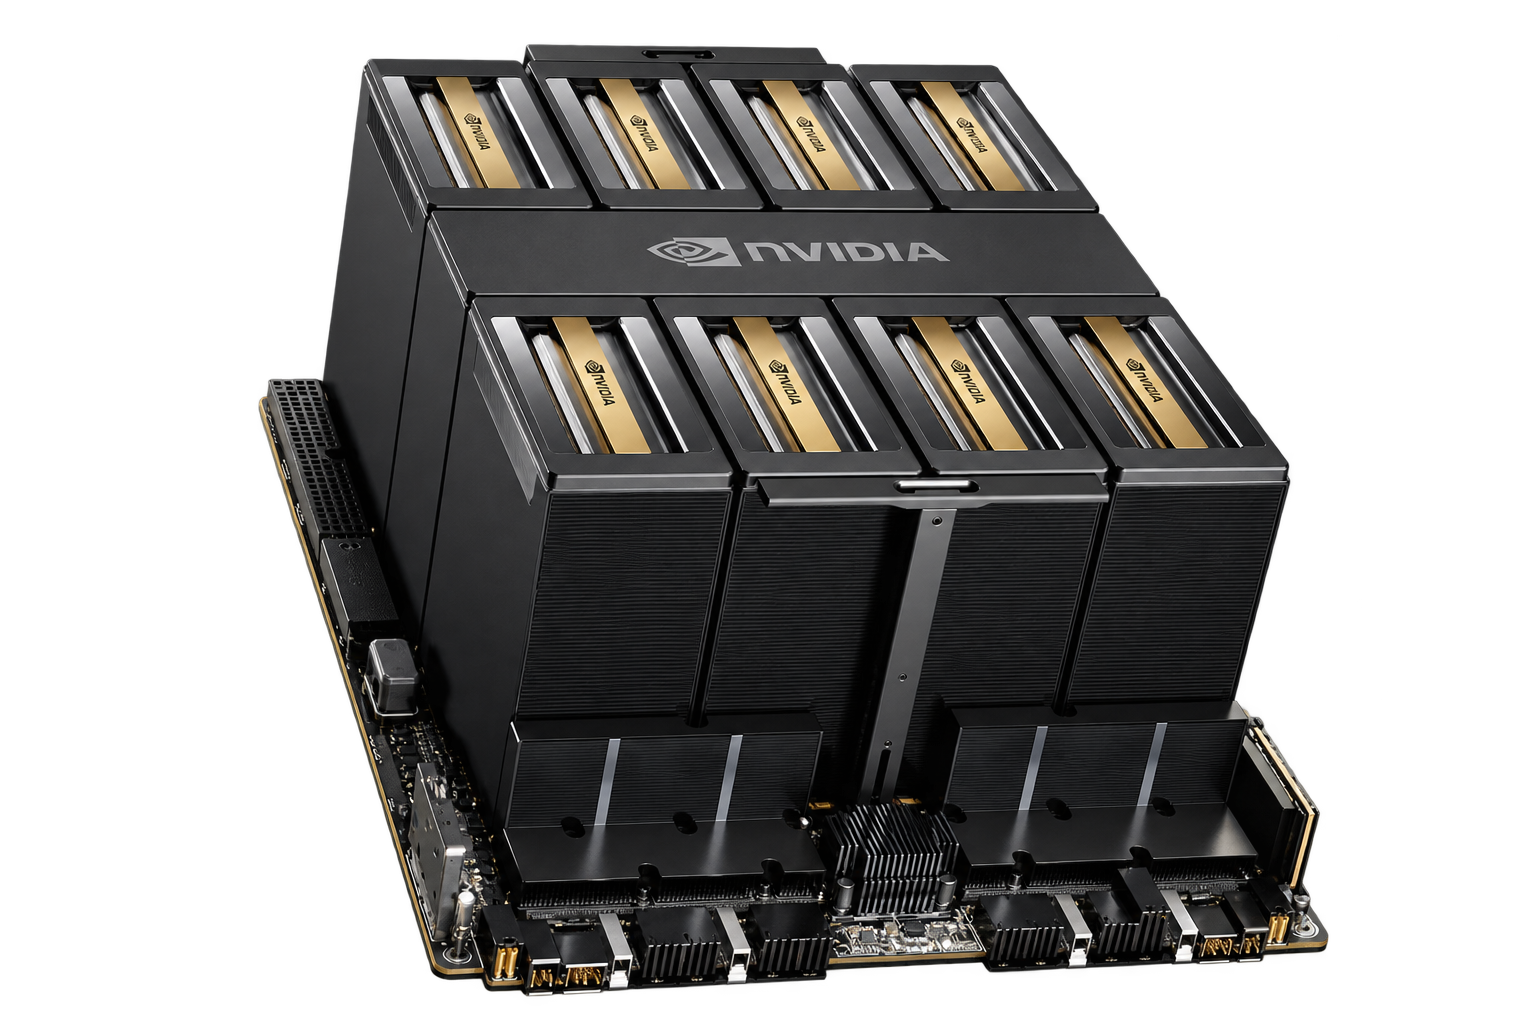
- Compute
- 8× B200 SXM
- GPU memory
- 1,440 GB HBM3e
- Runtime
- bLLM, encrypted end to end
BT B300 HGX
Blackwell UltraBlackthorn
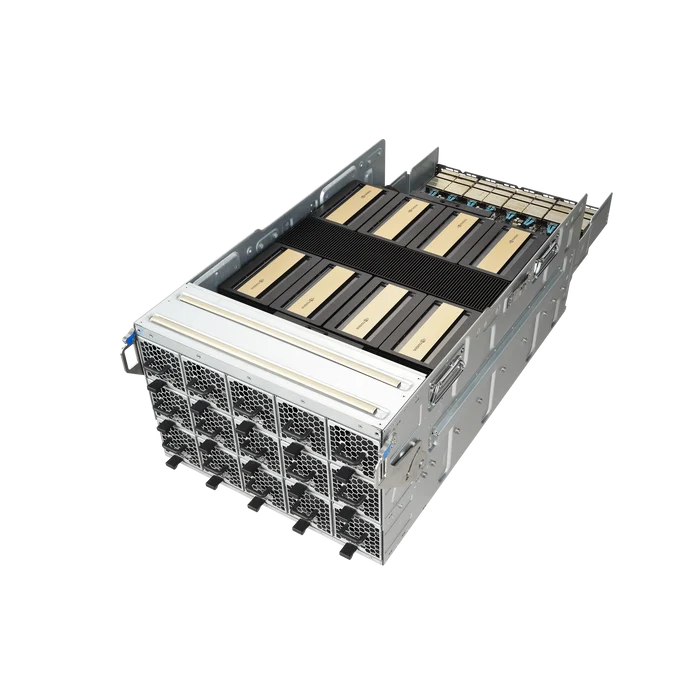
- Compute
- 8× B300 SXM
- GPU memory
- 2,304 GB HBM3e
- Runtime
- bLLM, encrypted end to end
Coming soon
The best open models, encrypted by API
Access the world’s best open-weight models through encrypted, pay-per-token inference.
 DeepSeek
 Moonshot AI
 Meta
 Z.ai
 Alibaba
 Mistral AI
 OpenAI
 Google

The next chapter
More coming soon
Explore the milestones ahead for Blackthorn and the Arcium network.